- Luminal has raised $25M in Series A funding led by Standard Capital.
- The company says its cloud now processes about 90 trillion tokens a month.
- The money funds engineering, go-to-market and support for non-Nvidia chips.
As demand for artificial intelligence grows, the cost of running models is becoming a major infrastructure challenge. Much of the industry still relies on Nvidia’s GPU ecosystem, while companies face limited hardware choices and complex optimisation requirements.
Luminal, a San Francisco-based AI infrastructure startup, has raised $25 million in Series A funding led by Standard Capital. All of its seed investors, including Y Combinator, Felicis, SagaVC, and Liquid, doubled down. The company did not disclose its valuation.
The US startup is developing a search compiler and inference cloud to help AI developers run models faster and more affordably across GPUs and application-specific integrated circuits, short for ASICs.
The funding will support engineering and go-to-market expansion, alongside broader compatibility with AI models and hardware platforms. With its $5.3 million seed round in November 2025, Luminal has raised about $30.3 million in total.
Founded to make AI inference more accessible
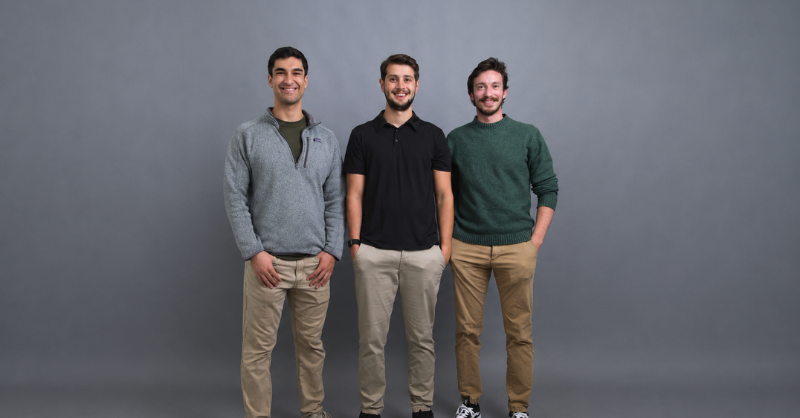
Luminal was co-founded by CEO Joe Fioti, a former Intel chip designer, with Matthew Gunton and Jake Stevens, who come from Amazon and Apple.
The company was part of Y Combinator’s Summer 2025 batch. Its seed round was led by Felicis, with angel investors including Paul Graham, Guillermo Rauch and Ben Porterfield. It began by building open-source tools on GitHub as AI adoption accelerated, after spotting demand for software that could optimise model performance across different chips.
Its central proposition is to reduce dependence on a single hardware ecosystem. Optimising AI models for different processors often requires specialised engineering and extensive manual tuning, making it hard for developers to switch between hardware providers.
Luminal’s search compiler addresses this by testing mathematically equivalent ways of executing a model on a particular chip and selecting the fastest implementation. Once optimised, the implementation can be reused for repeated workloads on the same model and hardware combination.
“We started by building in the open on GitHub as AI adoption took off, and quickly saw how much demand there was for a more efficient way to run AI models across different hardware. The cost of running AI shouldn’t limit who gets to build it. We’re building the infrastructure to make high-performance inference more accessible, giving developers more choice beyond NVIDIA’s ecosystem without forcing them to compromise on speed or cost,” said Joe Fioti, co-founder and CEO of Luminal.
A compiler and cloud for faster inference
Luminal combines its compiler with an inference cloud, allowing developers to deploy AI models without managing the underlying infrastructure.
The compiler optimises how models execute on available hardware, while the cloud provides access to those computing resources. Together, they aim to improve throughput and lower the cost of serving AI applications.
The platform targets workloads requiring continuous, high-volume inference, including AI coding agents, voice agents and image-editing tools. These applications need models to respond reliably to large numbers of requests, so infrastructure efficiency matters.
Since launching its public cloud following the seed round, the company says it has reached approximately 90 trillion tokens processed per month within four months.
Luminal also says it has committed a significant portion of these workloads to Amazon’s Trainium chips through a growing partnership with Amazon. The deal supports its strategy of helping customers use alternative AI hardware that can deliver competitive performance at lower costs.
Competition in AI inference optimisation
Luminal operates in a growing market of companies developing software and infrastructure to improve AI computing efficiency.
Palo Alto-based Standard Kernel raised $20 million in seed funding in March 2026, led by Jump Capital, to automate GPU kernel optimisation using AI. RadixArk, which emerged from the open-source SGLang project, was valued at about $400 million in January 2026, with Accel as lead investor.
Elsewhere, Finnish AI cloud provider Verda raised $117 million in April 2026, led by Lifeline Ventures, to expand its GPU cloud as an alternative to traditional hyperscalers. Larger inference provider Together AI raised $800 million at an $8.3 billion valuation in July 2026.
Unlike rivals, Luminal combines compiler-level optimisation with a managed inference cloud, while extending support beyond Nvidia GPUs to alternative processors such as Amazon Trainium.
Inference becomes a growing infrastructure market
The opportunity is expanding as AI applications move from model training towards continuous deployment and usage. Grand View Research estimates that the global AI inference software market was valued at $17.5 billion in 2025 and could reach $80.9 billion by 2033, growing at a compound annual rate of 21.1%.
For developers, inference costs directly affect the economics of running AI products. Using hardware more efficiently and requiring fewer resources per response can make applications cheaper to run at scale.
Luminal believes the broader AI infrastructure opportunity could reach $5 trillion, although this is the company’s estimate rather than an independent market forecast.
“Inference is the most important market in the world right now, not to mention the fastest-growing. We backed Luminal because of their deep technical expertise and demonstrated proof they can squeeze fantastic performance out of heterogeneous hardware. Luminal’s ability to get the most out of GPUs that have already been purchased and powered is incredibly high leverage,” said Dalton Caldwell, managing partner of Standard Capital and a former managing partner at Y Combinator.
Luminal envisions developers increasingly prioritising performance and cost over loyalty to a single chip ecosystem. So, can it make hardware flexibility work at production scale without compromising speed or reliability?